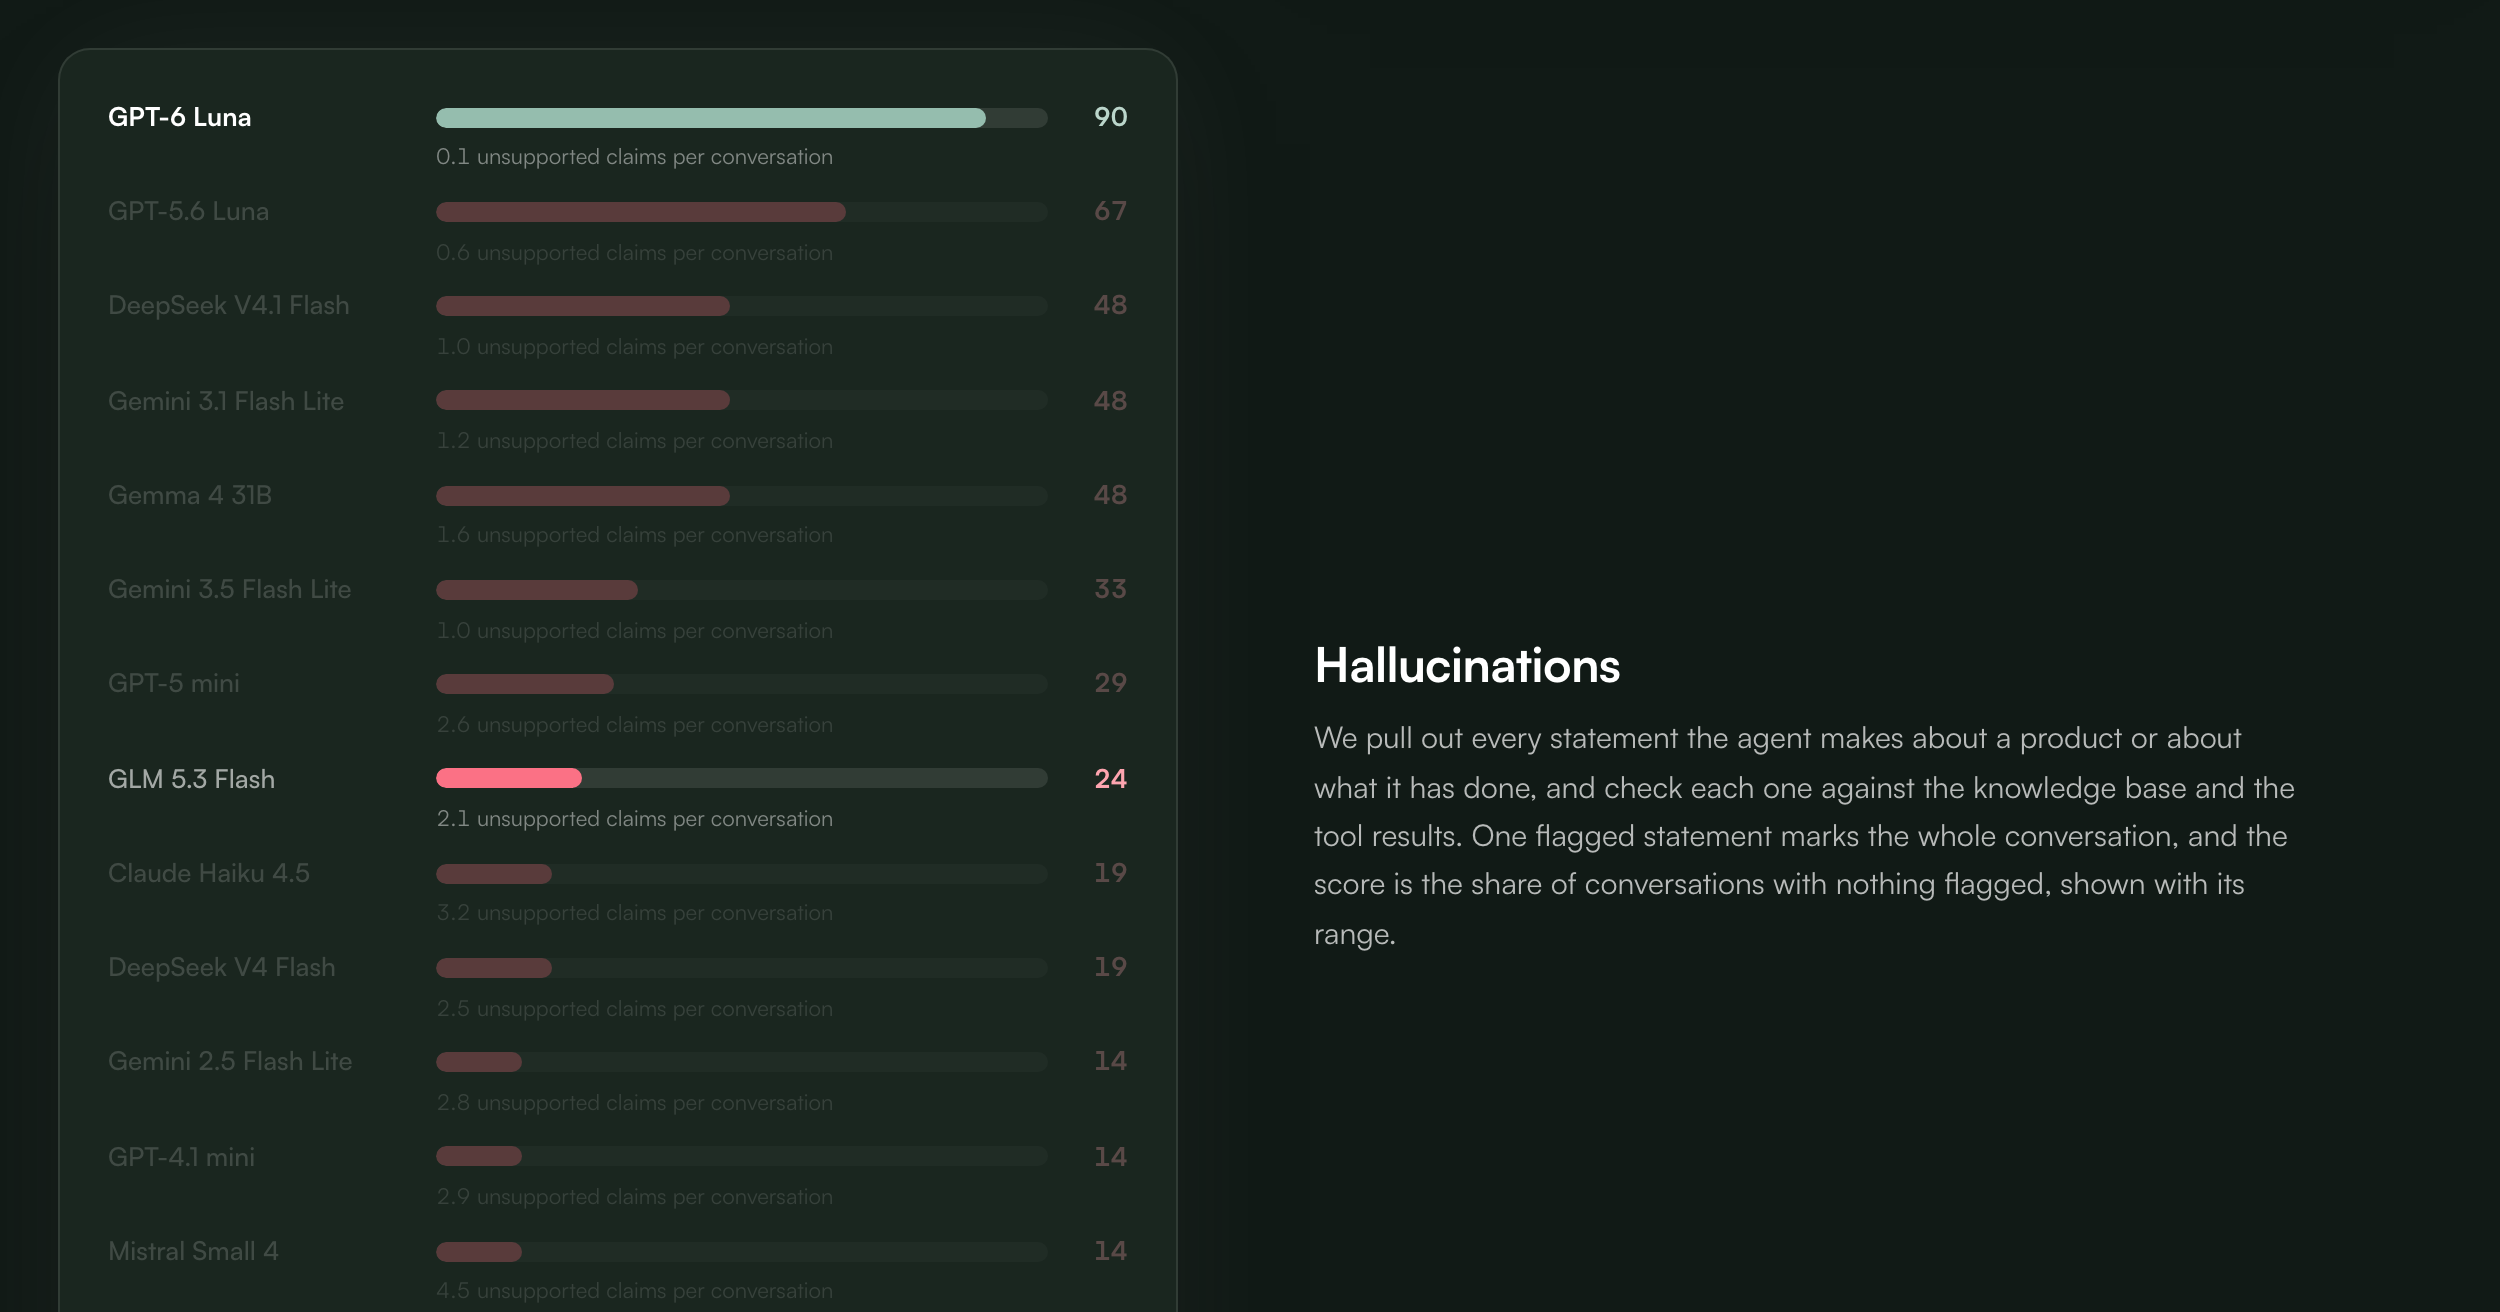
GPT-6 Luna vs GLM 5.3 Flash: the cost of saying too much
GLM 5.3 Flash supported 96% of its claims, yet only five of 21 conversations were clean. The difference exposes a blind spot in how teams measure agent reliability.
Writing on testing conversational AI agents: multi-turn failures, tool calling, hallucinations, and what catches them.
GLM 5.3 Flash supported 96% of its claims, yet only five of 21 conversations were clean. The difference exposes a blind spot in how teams measure agent reliability.
Mattias
A stronger model with higher scores looks like a free upgrade, until the agent that worked last week starts getting things wrong, quietly. Here is what happened when we ran one agent on two frontier models and changed nothing else.
Voxli
A customer opens your support agent with this:
Mahey Qadir
A customer is halfway through a return flow with your agent. They've shared the order number, the item and reason for the return. They then pause to ask: "Wait, do you offer…
Voxli
Most agent failures we see in pilots don't show up on prompt evals.
Voxli
Last week a failed tool call caused GPT-5.4-mini to cancel a real order simply because a customer asked a question involving cancellation. Here's a quick test that catches it.
Voxli
Expertise.ai is a known disruptor in the AI space, building AI sales agents that guide prospects through personalized flows. Here's how Voxli untangled their testing workflow.
Mahey Qadir
Recently, to assess AI Agent performance with tool calls, we executed the same multi-turn conversation across the three tiers of OpenAI's GPT-5.4: standard, mini, and nano.
Mahey Qadir
In our last post we covered the risks of agent speculation. Today we look at how to set up Voxli to catch those speculations using a feature called Hallucination detection.
Mahey Qadir
It's no surprise that hallucinations are a common known failure during agentic AI testing. The agent starts to overpromise, begins to fabricate answers and even claims that it…
Voxli